

大数据 银行业应用案例
A Portuguese banking institution ran a marketing campaign to convince potential customers to invest in bank term deposits. Information related to direct marketing campaigns of the bank is as follows. The marketing campaigns were based on phone calls. Often, the same customer was contacted more than once through phone, to assess if they would want to subscribe to the bank term deposit or not.
一家葡萄牙银行机构开展了一项营销活动,以说服潜在客户投资银行定期存款。 与银行的直接营销活动有关的信息如下。 市场营销活动基于电话。 通常,通过电话与同一个客户联系多次,以评估他们是否要订阅银行定期存款。
The following questions were answered by data analysis with Spark
Spark的数据分析回答了以下问题
- Load data and create a Spark data frame加载数据并创建一个Spark数据框
- Give marketing success rate. (No. of people subscribed / total no. of entries) 给出营销成功率。 (订阅人数/总参赛人数)
- Give marketing failure rate 给出营销失败率
- Maximum, Mean, and Minimum age of the average targeted customer平均目标客户的最高年龄,平均年龄和最低年龄
- Check the quality of customers by checking the average balance, median balance of customers通过检查平均余额,中位数余额来检查客户的质量
- Check if age matters in marketing subscription for deposit检查年龄是否与营销订阅中的存款有关
- Check if marital status mattered for subscription to deposit.检查婚姻状况是否对订金有重要意义。
- Check if age and marital status together mattered for subscription to deposit scheme 检查年龄和婚姻状况是否对订阅存款计划有重要影响
- Do feature engineering for the column — age and the right age effect on the campaign对列进行功能设计-年龄和正确的年龄对广告系列的影响
The dataset is from the banking sector with the following attributes
数据集来自银行业,具有以下属性
Features attributes: age, job, marital, education, default, balance, housing, loan, contact, day, month, duration, campaign, pdays, previous, poutcome.
功能属性:年龄,工作,婚姻,教育,默认,余额,住房,贷款,联系方式,日期,月份,持续时间,竞选活动,周日,以前,结果。
Target attributes: y
目标属性:y
From the attributes the column ‘y’ is important and it has a two-class, ‘yes’ and ‘no’. If the user is subscribed to a term deposit then it is ‘yes’ otherwise ‘no’.
从属性中,“ y”列很重要,它具有两类,“是”和“否”。 如果用户订阅了定期存款,则为“是”,否则为“否”。
Loading data and create Spark data frame
加载数据并创建Spark数据框
scala> val df = spark.read.format("csv").option("header","true").option("delimiter",     ";").load("banking.csv")#output:
df: org.apache.spark.sql.DataFrame = [age: string, job: string, ....
    15 more fields]
Here we are assigning our CSV file in a ‘df’ variable and the delimiter in this CVS file is not a comma but it is a semi-colon. To print all the variables we need to write a printSchema function.
在这里,我们在'df'变量中分配CSV文件,并且此CVS文件中的定界符不是逗号,而是分号。 要打印所有变量,我们需要编写一个printSchema函数。
scala> df.printSchema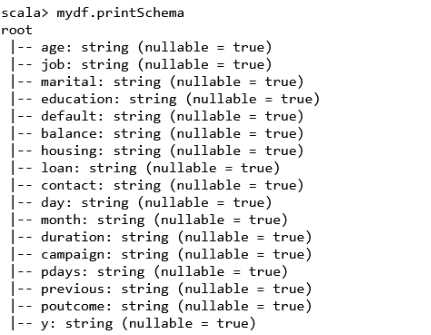
Give marketing success rate. (No. of people subscribed / total no. of entries)
给出营销成功率。 (订阅人数/总参赛人数)
For the success rate, we need to find the total number of ‘yes’ entries in the target column and divide it with the total number of entries. To count the total number of ‘yes’ by the filter function.
为了获得成功率,我们需要在目标列中找到“是”条目的总数,然后将其除以条目总数。 通过过滤功能计算“是”的总数。
scala> val sub_count = df.filter($"y"==="yes").count().toDouble#output:
sub_total: Double = 5289.0
To find the total values of the entries
查找条目的总值
scala> val totalcount = df.count().toDouble#output:
totalcount: Double = 45211.0
To find the success rate just divide the sub_count to the total count.
要找到成功率,只需将sub_count除以总数即可。
scala> val success_rate = sub_total/totalcount#output:
success_rate: = Double = 0.116984
Give marketing failure rate
给出营销失败率
To get the failure rate, we need to divide the total_failure to the total count.
为了获得失败率,我们需要将total_failure除以总数。
scala> val fail_count = df.filter($"y"==="no").count().toDoublescala> val failure_rate = fail_count/totalcount#output:
failure_rate: Double = 0.883015
Maximum, Mean, and Minimum age of average targeted customer
平均目标客户的最高年龄,平均年龄和最低年龄
When we see the dataset the age column has a different number of people with different ages and it is in numeric values. So, we need to find out the maximum age, minimum age and the average age of the people.
当我们看到数据集时,“年龄”列具有不同数量的具有不同年龄的人,并且是数字值。 因此,我们需要找出人们的最高年龄,最低年龄和平均年龄。
scala> sql("select min(age), avg(age), max(age) from banking").show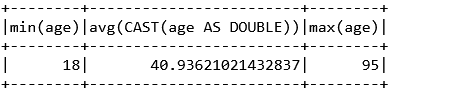
Check quality of customers by checking average balance, median balance of customers
通过检查平均余额,客户中位数余额来检查客户质量
This is the next step to find the average and median balance of customers.
这是查找客户平均余额和中位数余额的下一步。
scala> sql("select avg(balance), percentile_approx(balance, 0.5) from banking").show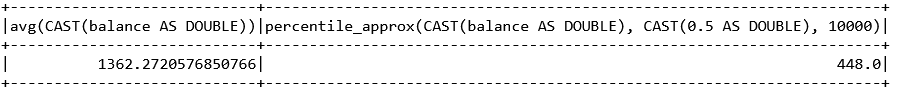
Check if age matters in marketing subscription for deposit
检查年龄是否与营销订阅中的存款有关
For deposit, it is important that which age group people are more in numbers and in the code, the desc is descending order in this is the total number of every particular age.
对于存款,重要的是哪个年龄段的人的人数更多,并且在代码中,降序是降序排列,这是每个特定年龄段的总数。
scala> sql("select age, count(*) as age_count from banking where y = 'yes' group by age order by age_count desc").show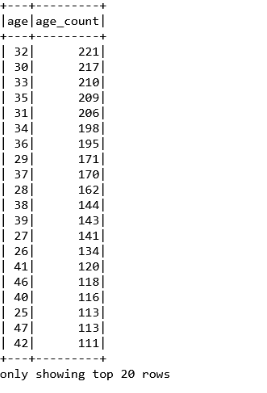
Check if marital status mattered for subscription to deposit.
检查婚姻状况是否对订金有重要意义。
scala> sql("select marital, count(*) as no from banking where y = 'yes' group by marital order by no desc").show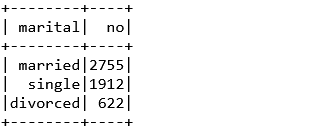
Check if age and marital status together mattered for subscription to deposit scheme
检查年龄和婚姻状况是否对订阅存款计划有重要影响
The code is counting the age and marital status and creating a new column as subscription of counts
该代码正在计算年龄和婚姻状况,并创建一个新列作为计数的订阅
scala> sql("select age, marital, count(*) as subscription from banking where y = 'yes' group by age, marital order by subscription desc").show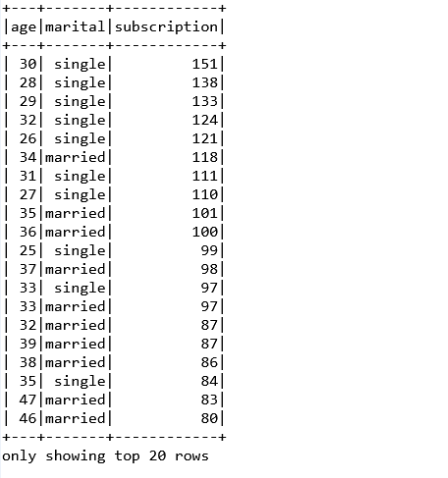
Do feature engineering for column — age and find right age effect on campaign
做专栏的专案工程-年龄并找出正确的年龄对广告系列的影响
The main objective of this feature engineering is that which age group is more important for subscriptions
此功能工程的主要目标是哪个年龄段对订阅更重要
scala> sql("select case when age<25 then 'Young' when age between 25 and 60 then 'Middle Age' when age>60 then 'Old' end as age_category, count(1) from banking where y='yes' group by age_category by 2 desc").show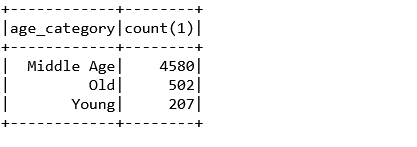
You can reach me at my LinkedIn link here and on my email: design4led@gmail.com.
你可以在我的LinkedIn链接到我这里design4led@gmail.com:和我的电子邮件。
My Previous Articles:
我以前的文章:
大数据 银行业应用案例


 已为社区贡献2条内容

所有评论(0)