python 使用cookies,用requests爬去淘宝页面
·
大学慕课《python网络爬虫与信息提取》的源代码
https://www.icourse163.org/learn/BIT-1001870001?tid=1206951268#/learn/content?type=detail&id=1211970252&cid=1215042973
具体代码如下
#CrowTaobaoPrice.py
import requests
import re

def getHTMLText(url):
    try:
        r = requests.get(url, timeout=30)
        r.raise_for_status()
        r.encoding = r.apparent_encoding
        return r.text
    except:
        return ""

def parsePage(ilt, html):
    try:
        plt = re.findall(r'\"view_price\"\:\"[\d\.]*\"',html)
        tlt = re.findall(r'\"raw_title\"\:\".*?\"',html)
        for i in range(len(plt)):
            price = eval(plt[i].split(':')[1])
            title = eval(tlt[i].split(':')[1])
            ilt.append([price , title])
    except:
        print("")

def printGoodsList(ilt):
    tplt = "{:4}\t{:8}\t{:16}"
    print(tplt.format("序号", "价格", "商品名称"))
    count = 0
    for g in ilt:
        count = count + 1
        print(tplt.format(count, g[0], g[1]))

def main():
    goods = '书包'
    depth = 3
    start_url = 'https://s.taobao.com/search?q=' + goods
    infoList = []
    for i in range(depth):
        try:
            url = start_url + '&s=' + str(44*i)
            html = getHTMLText(url)
            parsePage(infoList, html)
        except:
            continue
    printGoodsList(infoList)

main()
因为淘宝的改进,这个代码爬不出来。需要伪装headers
找cookies
链接: 淘宝.
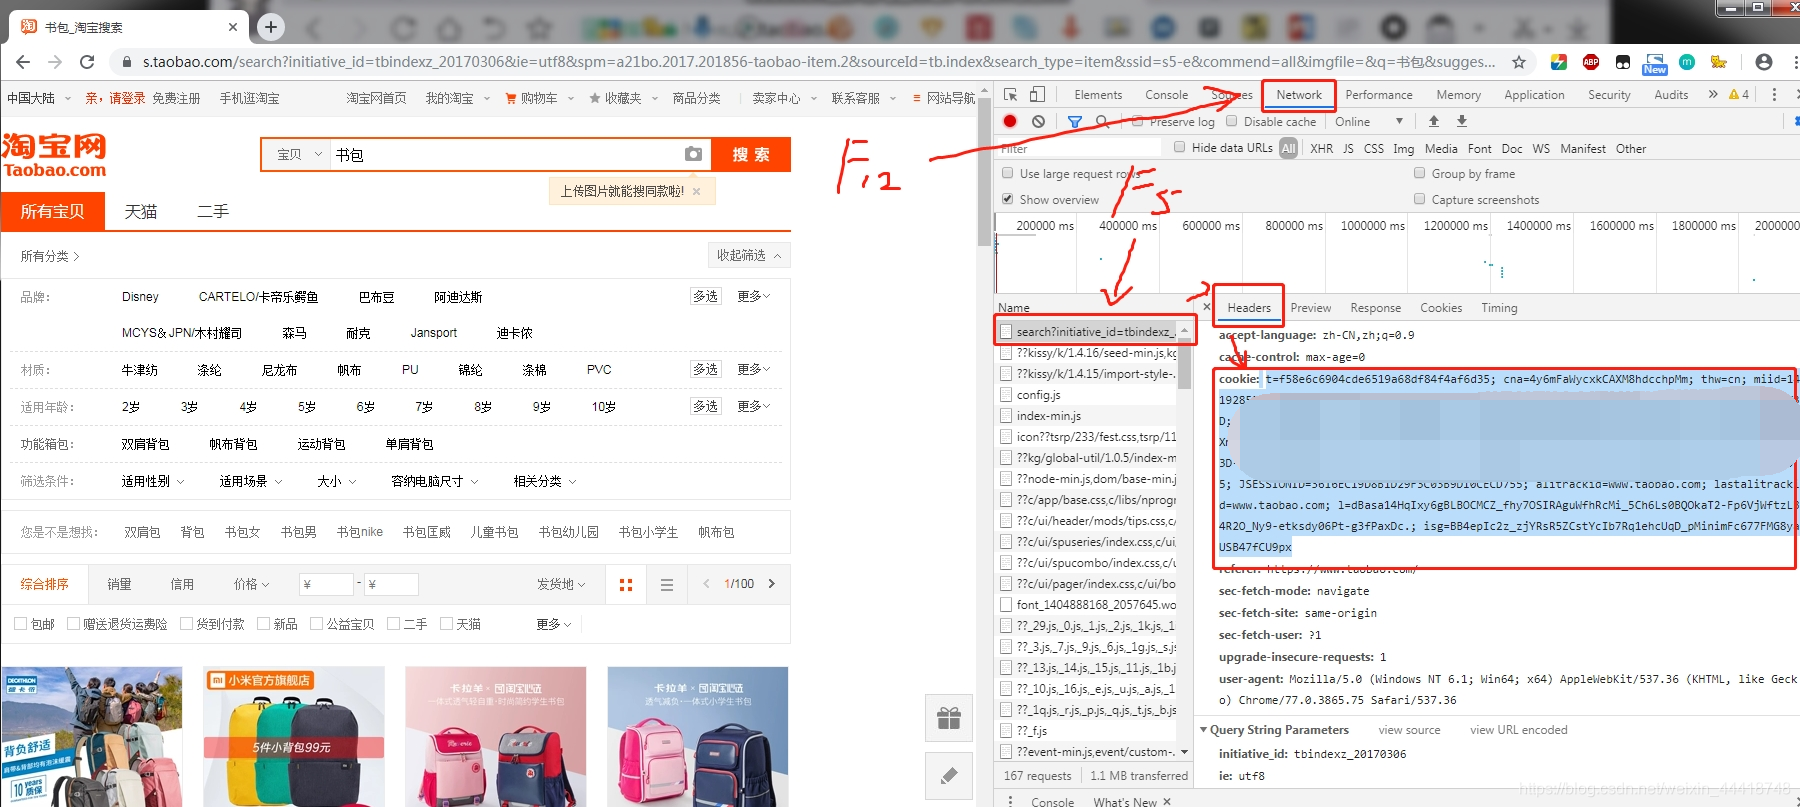
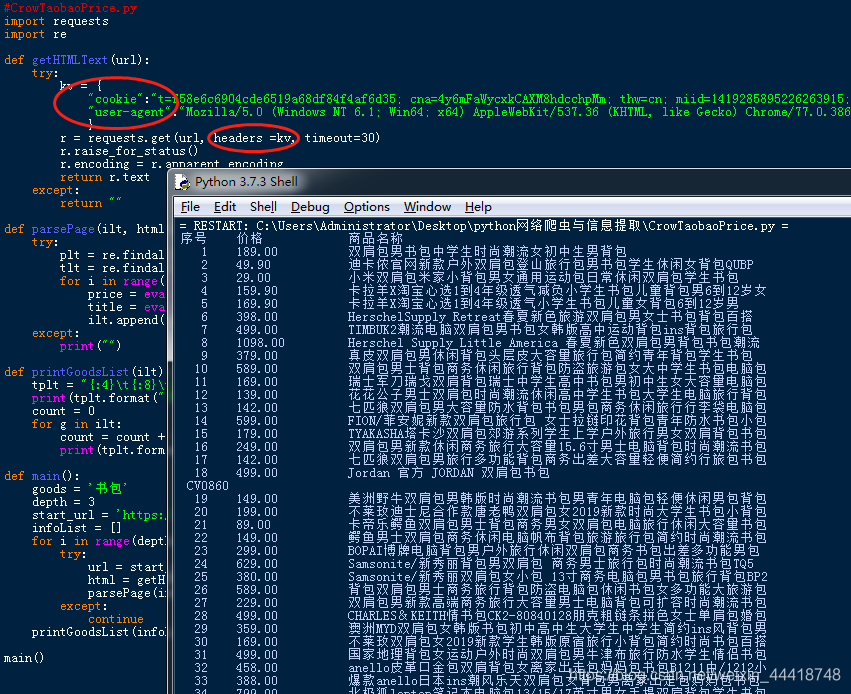
成功的代码,更改要点见图

北京人形旗下天工造物具身智能开源社区,聚焦具身天工与慧思开物两大平台
更多推荐
 5
 0
- 0


 已为社区贡献1条内容

所有评论(0)